TII Releases Falcon-ASR Arabic Speech Model
Abu Dhabi's Technology Innovation Institute introduced Falcon-ASR, a 1.6B parameter model that outperforms larger competitors on Arabic and regional speech recognition benchmarks.
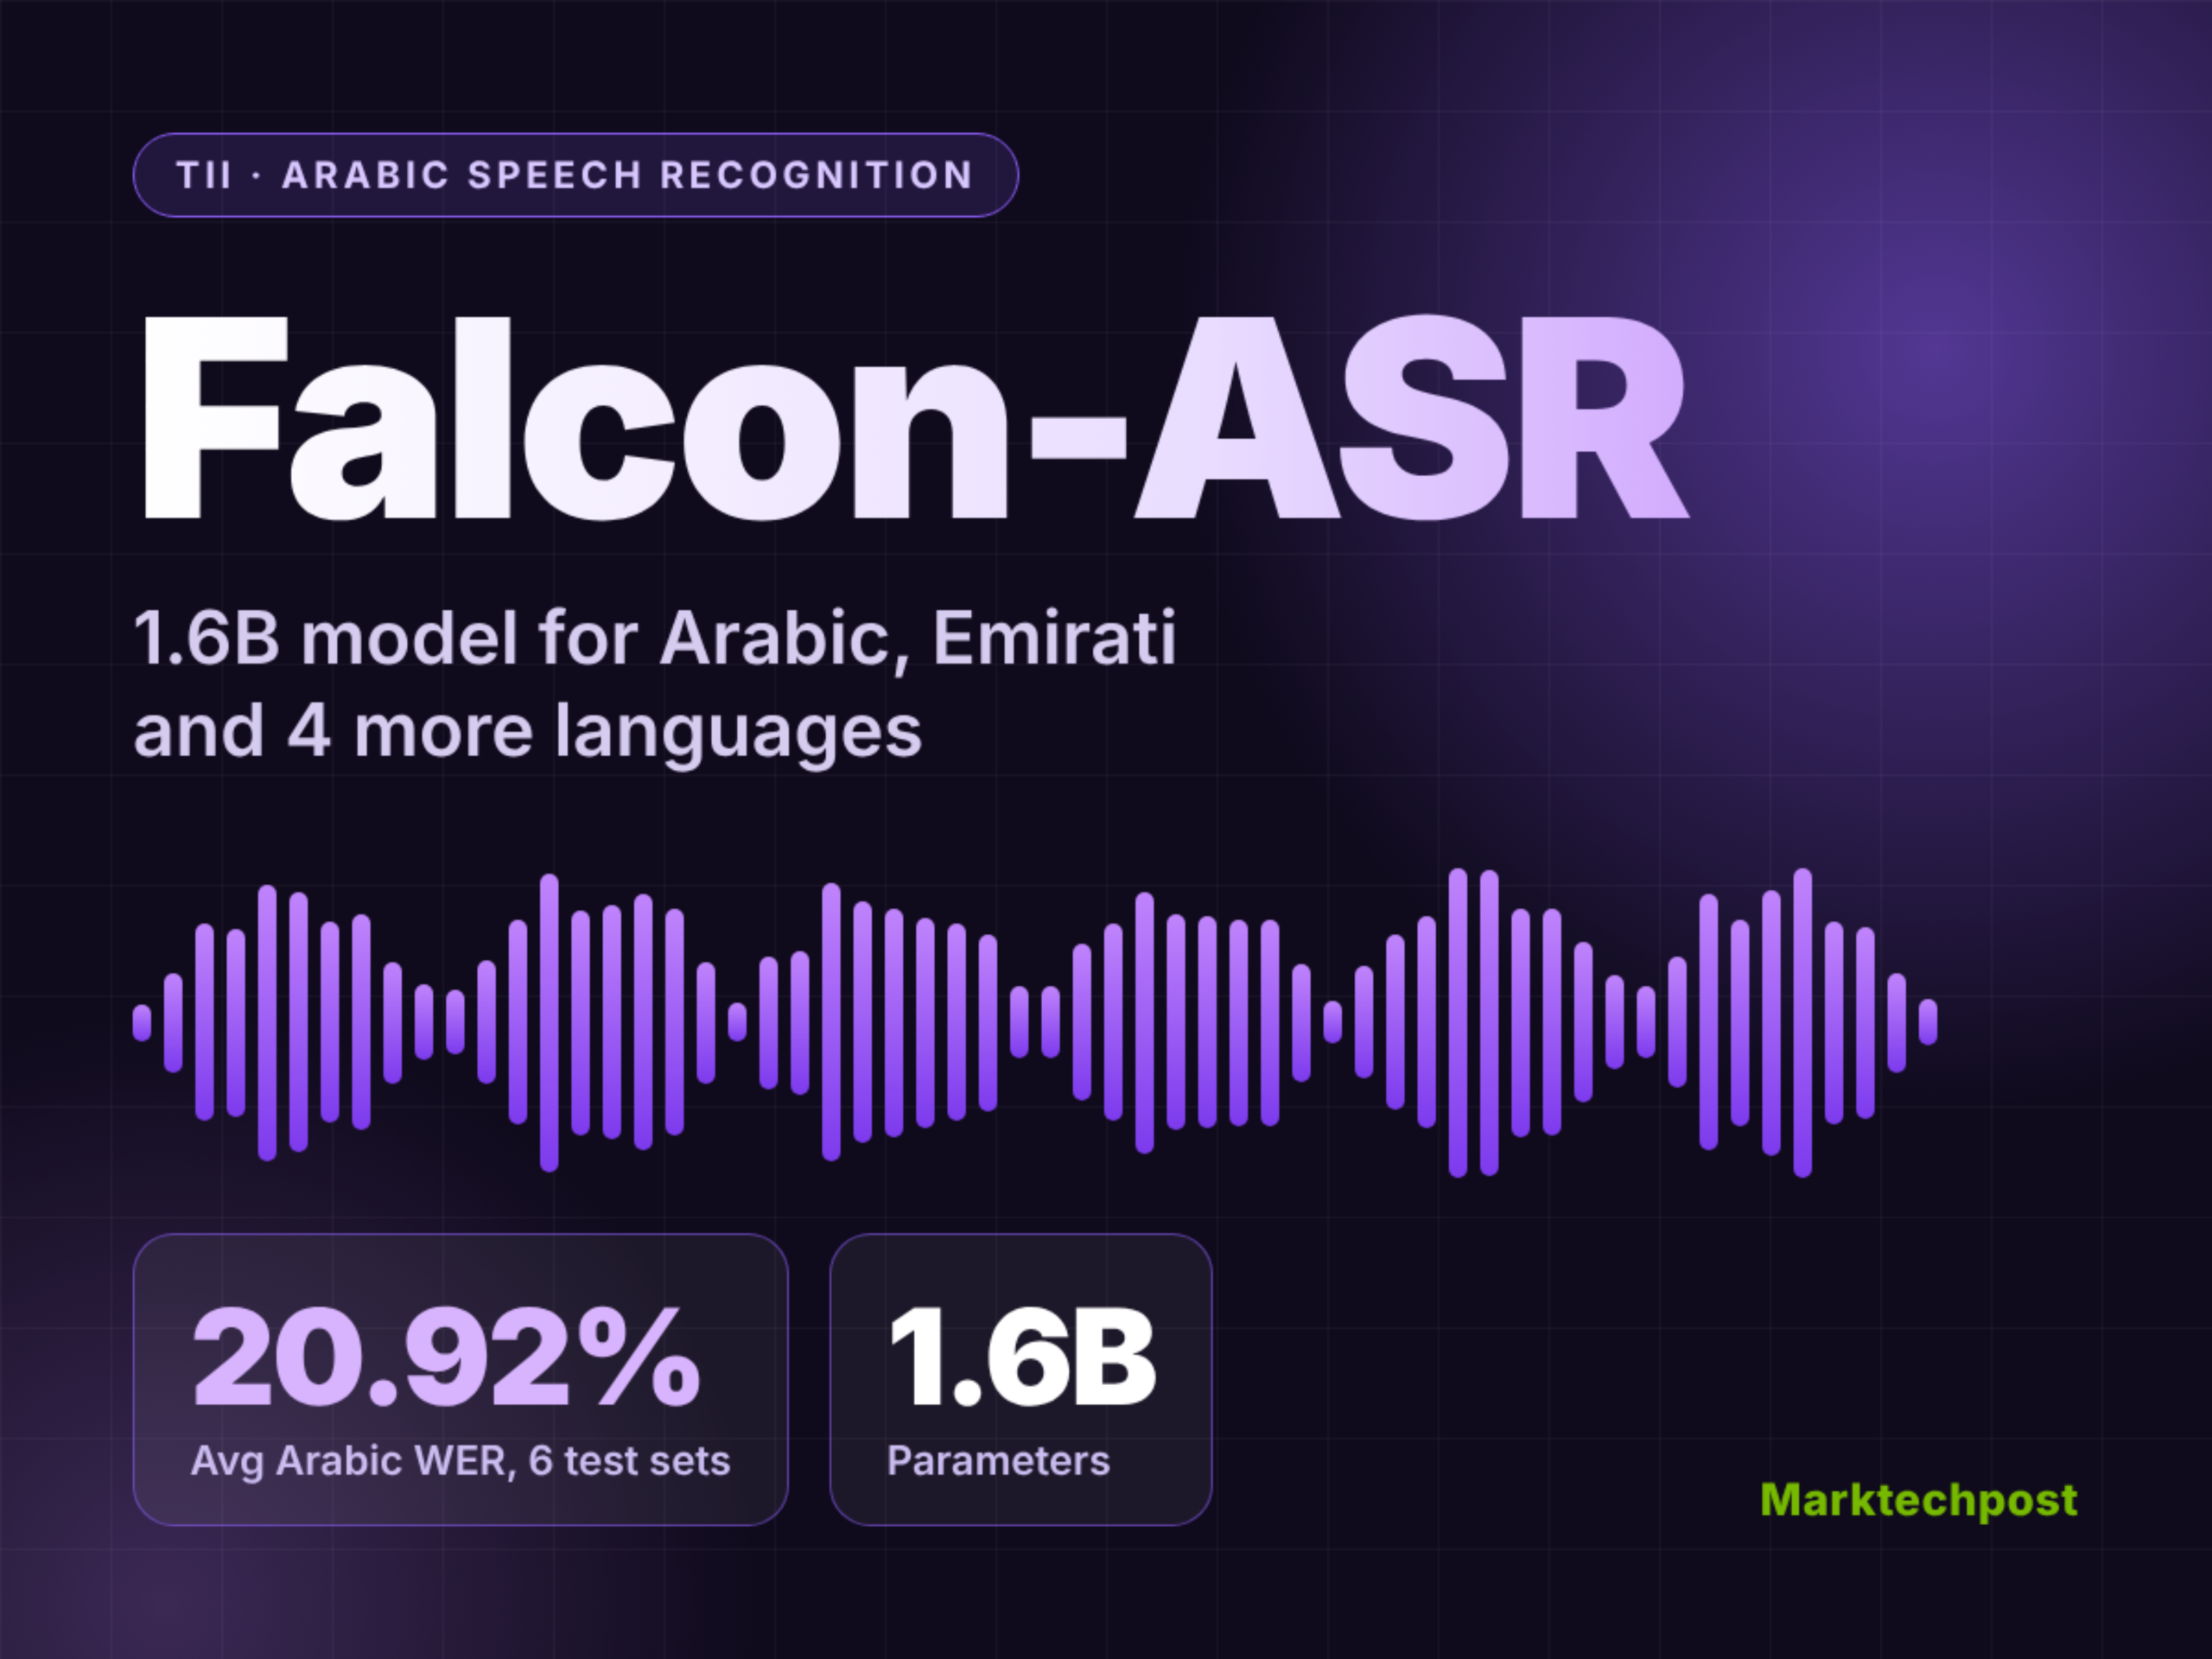
The Technology Innovation Institute (TII) in Abu Dhabi has announced Falcon-ASR, a 1.6-billion-parameter speech recognition model built to transcribe Arabic dialects, Modern Standard Arabic, English, French, Spanish, and Portuguese using a single set of weights. In internal evaluations matching the Open Universal Arabic ASR Leaderboard protocol across six test sets, Falcon-ASR achieved a 20.92% average word error rate (WER) and an 8.79% character error rate (CER). This performance puts it ahead of competing models, including the 2.35B-parameter Audar-ASR-V1-Turbo at 23.17% WER, Cohere Transcribe Arabic at 25.87% WER, and the 7.0B-parameter omniASR LLM at 28.32% WER.
The model places a strong focus on everyday spoken dialects, particularly Emirati Arabic. On a private Gulf test set curated by TII, Falcon-ASR scored a 22.73% WER and 10.19% CER, outperforming Qwen3-Omni-30B-A3B-Instruct (which registered 26.80% WER with 3B active parameters), Audar-ASR-V1-Turbo at 27.89% WER, and Qwen3-ASR-1.7B at 31.52% WER. Across seven English evaluation sets from the Hugging Face Open ASR Leaderboard, Falcon-ASR posted a 5.74% mean WER, ranging from 1.75% on LibriSpeech clean to 11.86% on Earnings-22, placing it alongside Qwen3-ASR-1.7B's 5.76% average.
Building on TII's Falcon3-Audio architecture, which pairs Whisper encoders with instruction-tuned language models trained on under 30,000 hours of audio, Falcon-ASR automatically identifies languages without needing manual flags. It also returns word-level timestamps to support indexing, transcription, and subtitling workflows. Audio training involved heavy data augmentation, including background noise, overlapping conversations, telephony effects, and variations in speed and pitch.
For practical deployments, Falcon-ASR demonstrates that specialized 1.6B-parameter models can surpass much larger general-purpose architectures like 30B multimodal systems in dialectal speech tasks. However, developers cannot yet deploy the model locally or via self-hosting, as TII has not released open weights, quantized variants, or an open-source license. Current access is restricted to a Hugging Face web demo processing audio clips up to 60 seconds or 20 megabytes, though native applications and API access are planned for future release.
This is our own summary of reporting by MarkTechPost